03 Oct 2024

why I’m turning off Firefox ad tracking: the PPA paradox
Update: The
privacy-preserving attribution
feature is not present in the
current release of Firefox. However, Mozilla is collaborating with the
Big
Tech companies to push it forward at W3C. (update) More on
that: The
advertising cartel coming to your web browser
There are still a bunch of other advertising features in Firefox to check and turn off.
Original post follows.
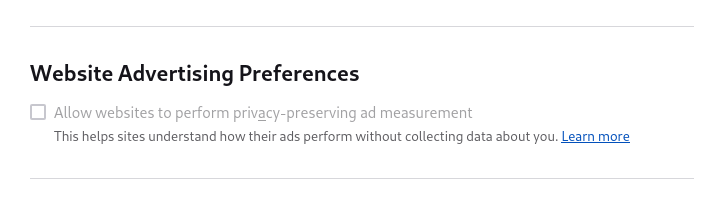
I am turning off Privacy-preserving attribution
(PPA), the controversial
Mozilla/Meta
advertising feature in Firefox. Yes, according to the documentation,
there are some good things about PPA compared to cookies:
You theoretically can’t be identified individually as the same person who saw an ad and then bought something
A site can’t tell if you have PPA on or off
Those are both interesting and desirable properties, and the PPA system, if implemented correctly and run honestly, does not look like a problem on its own. So why are people creeped out by it?
That creeped-out feeling is not coming from privacy math ignorance, it’s people’s inner behavioral economists warning about an information imbalance. Just like people who grow up playing ball can catch a ball without consciously doing calculus, people who grow up in market economies get a pretty good sense of markets and information, which manifests as a sense of being creeped out when something about a market design doesn’t seem right.
The problem is not the design of PPA on its own, it’s that PPA is
being proposed as something to run on the real Web, a place where you
can find both the best legit ad-supported content and the most
complicated scams. And that creates a PPA paradox: this
privacy-preserving
attribution tracking feature, if it catches
on, will tend to increase the amount of surveillance. PPA
doesn’t have all of the problems
of privacy-enhancing technologies in web browsers, but this is a big
one.
Briefly, the way that PPA is designed to work is that sites that run
ads will run JavaScript to request that the browser store
impression
events to keep a record of the ad you saw, and then a
site where you buy stuff can record a conversion
and then get a
report to find out which sites the people who bought stuff had seen ads
on. The browser doesn’t directly share the impression events with the
site where you buy stuff. It generates an encrypted message that might
or might not include impressions, then the site passes those encrypted
messages to secure services to do math on them and create an aggregated
report. The report doesn’t make it possible to match any individual ad
impression to any individual sale.
So, as a web entrepreneur willing to bend the rules, how would you
win
PPA? You could make a site where people pay attention to the
ads, and hope that gets them to buy stuff, so you get more ad money that
way. The problem with that is that legit ad-supported content and legit,
effective advertising are both hard. Not only do you need to make a good
site, the advertisers who run their ads on it need to make effective
ads in order for you to win this way. An easier way to win the PPA game
is to run a crappy site and then (1) figure out who’s about to buy, (2)
trick those people into visiting your crappy site, and (3) tell the
browser to store an impression before the sale you predicted, so that
your crappy site gets credit for making the sale. And steps 1 and 2 work
better and better the more surveillance you can do, including tracking
people between web and non-web activity, smart
TV mics, native mobile SDKs, server-to-server CAPIs, malware, use
your imagination.
(Update 14 Oct 2024) PPA has an antitrust problem, too. In a
market where the
average user has their activity passed to Meta by thousands of
companies, Meta has a large advantage when training a machine
learning system to steal conversions
by placing an ad in front of
someone who would be likely to buy anyway. With PPA, a large
surveillance company would not have to deliberately tell anyone to do
fraud, or write code to do fraud. Instead, ML systems designed to
win
PPA would learn
to do fraud, since if you have the
surveillance data anyway, fraud is the quickest, easiest way to get
money. (Like I said, legit conversions are hard.) And unlike what
happened in legacy fraud cases like Uber
v. Fetch, with PPA enough data is deliberately obfuscated to make
the fraud impossible to track down. Only a few large companies have the
combination of ML and large inflows of user data to make this kind of
invisible, deniable fraud possible, so PPA looks like a tool for
problematic concentration in the Internet and advertising
businesses.
Of course, attribution stealing schemes are a thing with conventional cookie and mobile app tracking, too. And they have been for quite a while. But conventional tracking generally produces enough extra info to make it possible to do more interesting attribution systems that enable marketers to figure out when legit and not-so-legit conversions are happening. If you read Mobile Dev Memo by Eric Seufert and other high-end marketing sites, there is a lot of material about more sophisticated attribution models than what’s possible with PPA. Marketers have a constant set of stats problems to solve to figure out which of the ads are going to influence people in the direction of buying stuff, and which ad money is being wasted because it gets spent on claiming credit for selling a thing that customers were going to buy anyway. PPA doesn’t provide the info needed to get good answers for those stats problems—so what works like a privacy feature on its own would drive the development and deployment of more privacy risks. I’m turning it off, and I hope that enough people will join me to keep PPA from catching on.